Technical SEO Foundations: From Crawlability to Measurable Growth

An engineering-focused guide to crawl paths, indexation, architecture, performance, structured data and evidence-based technical SEO audits.
Technical SEO is frequently presented as a collection of isolated checks: submit a sitemap, add canonical tags, improve speed, and fix broken links. Those tasks matter, but the checklist misses the central purpose. Technical SEO creates the conditions under which a search engine can discover, interpret, select, and confidently serve the right page. It is an information engineering discipline that connects server behavior, site architecture, templates, content, and measurement.
A technically clean website cannot compensate for weak or undifferentiated content. Equally, excellent content can remain invisible when crawlers encounter inconsistent URLs, blocked resources, duplicate templates, unreliable rendering, or an architecture that hides important pages. Sustainable search performance requires both meaning and delivery.
Understand the search pipeline
A page must pass through several stages before it can earn useful visibility. The search engine discovers a URL through links, sitemaps, or previous knowledge. It fetches the response, processes the HTML and resources, decides whether the page belongs in its index, interprets its meaning and relationships, and later evaluates it for relevant searches. A problem early in this sequence prevents later optimization from having effect.
This model helps prioritize investigations. If an important page is not discovered, rewriting its title is premature. If the server returns inconsistent status codes, structured data is not the first concern. If many duplicate URLs compete for selection, producing more similar pages increases ambiguity. Technical SEO should locate the earliest broken condition and fix the system that produces it.
Make server responses truthful
HTTP status codes are basic but powerful signals. A successful page should return 200. A permanently moved resource should redirect once to its final replacement. A missing page should return 404 or 410, even when it displays a helpful custom design. Returning 200 for an error page creates a soft 404 and asks search engines to infer failure from content.
Redirect chains consume time, complicate crawling, and preserve unnecessary historical steps. Internal links should point directly to canonical destinations. Choose consistent rules for HTTPS, preferred hostname, trailing slashes, and case, then apply them predictably. Avoid redirecting every missing URL to the homepage; it confuses visitors and destroys the distinction between missing and valid resources.
Reliability is also an SEO concern. Intermittent database errors, slow timeouts, and overloaded hosting can reduce crawl efficiency and user satisfaction. Monitor server errors and response times using real logs rather than waiting for a search report to reveal a pattern weeks later.
Design crawl paths through useful architecture
A sitemap is a discovery aid, not a replacement for navigation. Important pages should be reachable through ordinary internal links from relevant parts of the site. A clear hierarchy communicates priority and context: the home page introduces the business, service pages define offers, project pages demonstrate outcomes, and articles deepen specific topics.
Keep valuable pages within a reasonable number of meaningful clicks. This does not require a flat site where every page appears in the main navigation. Contextual links are often stronger because they explain the relationship. An article about internal workflow software can link to a relevant service and to a case study showing implementation. Breadcrumbs expose hierarchy to users and machines.
Orphan pages—URLs present only in a sitemap or external link—lack internal context and receive no navigational support. Find them by comparing known URLs from sitemaps, analytics, server logs, and crawls. Then decide whether to integrate, redirect, archive, or remove them. The goal is not to maximize the number of indexed URLs; it is to maintain a coherent set of pages worth finding.
Turn topics into an information system
Content architecture should reflect how the business can provide distinctive value. Broad topics such as “web development” contain many intents. A useful system separates commercial pages from educational articles while connecting them. A service page explains scope and fit. A project page supplies evidence. An article answers a focused question with enough depth to be independently valuable.
Topic clusters should emerge from real expertise, customer questions, and search evidence—not from producing dozens of superficial keyword variations. One authoritative article can address closely related formulations when the underlying intent is the same. Separate pages are justified when visitors need materially different answers, formats, or actions.
Use descriptive headings to expose the logic of a page. The primary heading should identify its central subject. Subsequent headings should represent meaningful sections, not decorative text sizes. This makes long content easier to scan, improves accessibility, and gives parsing systems a stable outline.
Control duplication and canonicalization
Duplicate content is often a URL-management problem rather than plagiarism. Tracking parameters, filter combinations, print views, inconsistent hostnames, and CMS archives can expose similar content through multiple addresses. Decide which URL should represent each resource, link to it consistently, include it in the sitemap, and use canonical tags as confirmation.
A canonical tag is a hint, not permission to maintain chaotic URLs. Search engines may ignore it when signals conflict. Redirect true duplicates when alternatives have no independent visitor value. Keep canonical pages self-referential. Do not canonicalize unrelated pages simply to remove them from reports; use appropriate access or indexing controls based on the actual requirement.
Multilingual sites require special care. Each language version should have its own stable URL and should declare language alternates only when equivalent pages genuinely exist. Sending every alternate to a homepage or nonexistent translation creates a misleading network. The page language, visible content, URL, canonical, and hreflang signals should agree.
Deliver meaningful HTML efficiently
Search engines can process JavaScript, but that capability does not make every rendering strategy equally reliable. Essential titles, headings, copy, links, and structured navigation should be present in the initial HTML whenever practical. Server-rendered pages reduce dependency on client execution and often improve performance for visitors on modest devices.
Keep robots controls explicit. A blocked URL cannot be crawled to see a noindex directive inside it. Use robots.txt primarily to manage crawling of known technical areas, not to remove sensitive information. Sensitive resources require authentication or server-level denial. Meta robots and X-Robots-Tag control indexing for accessible documents.
Treat Core Web Vitals as product signals
Core Web Vitals translate aspects of experience into measurable signals. Largest Contentful Paint reflects how quickly the main visible content appears. Interaction to Next Paint reflects responsiveness after user input. Cumulative Layout Shift reflects visual stability. They matter because delays and movement interfere with understanding and action.
Improve the causes, not only the score. Optimize and size the likely largest image. Preload truly critical assets carefully. Reduce render-blocking work. Reserve dimensions for images and embeds. Break long JavaScript tasks and avoid third-party scripts that provide little business value. Test actual templates because an excellent homepage does not prove that article or project pages perform equally well.
Laboratory tests are reproducible and useful for diagnosis. Field data shows what real visitors experienced across devices and networks. Use both. A local test may reveal a specific blocking stylesheet, while field data may show that a problem affects only mobile users or a particular template.
Use structured data to clarify, not decorate
Structured data expresses entities and relationships in a machine-readable vocabulary. For a professional portfolio, appropriate types may describe a person, organization, services, projects, breadcrumbs, frequently asked questions, and articles. The markup must match visible content and should be generated from the same source data so it does not become stale.
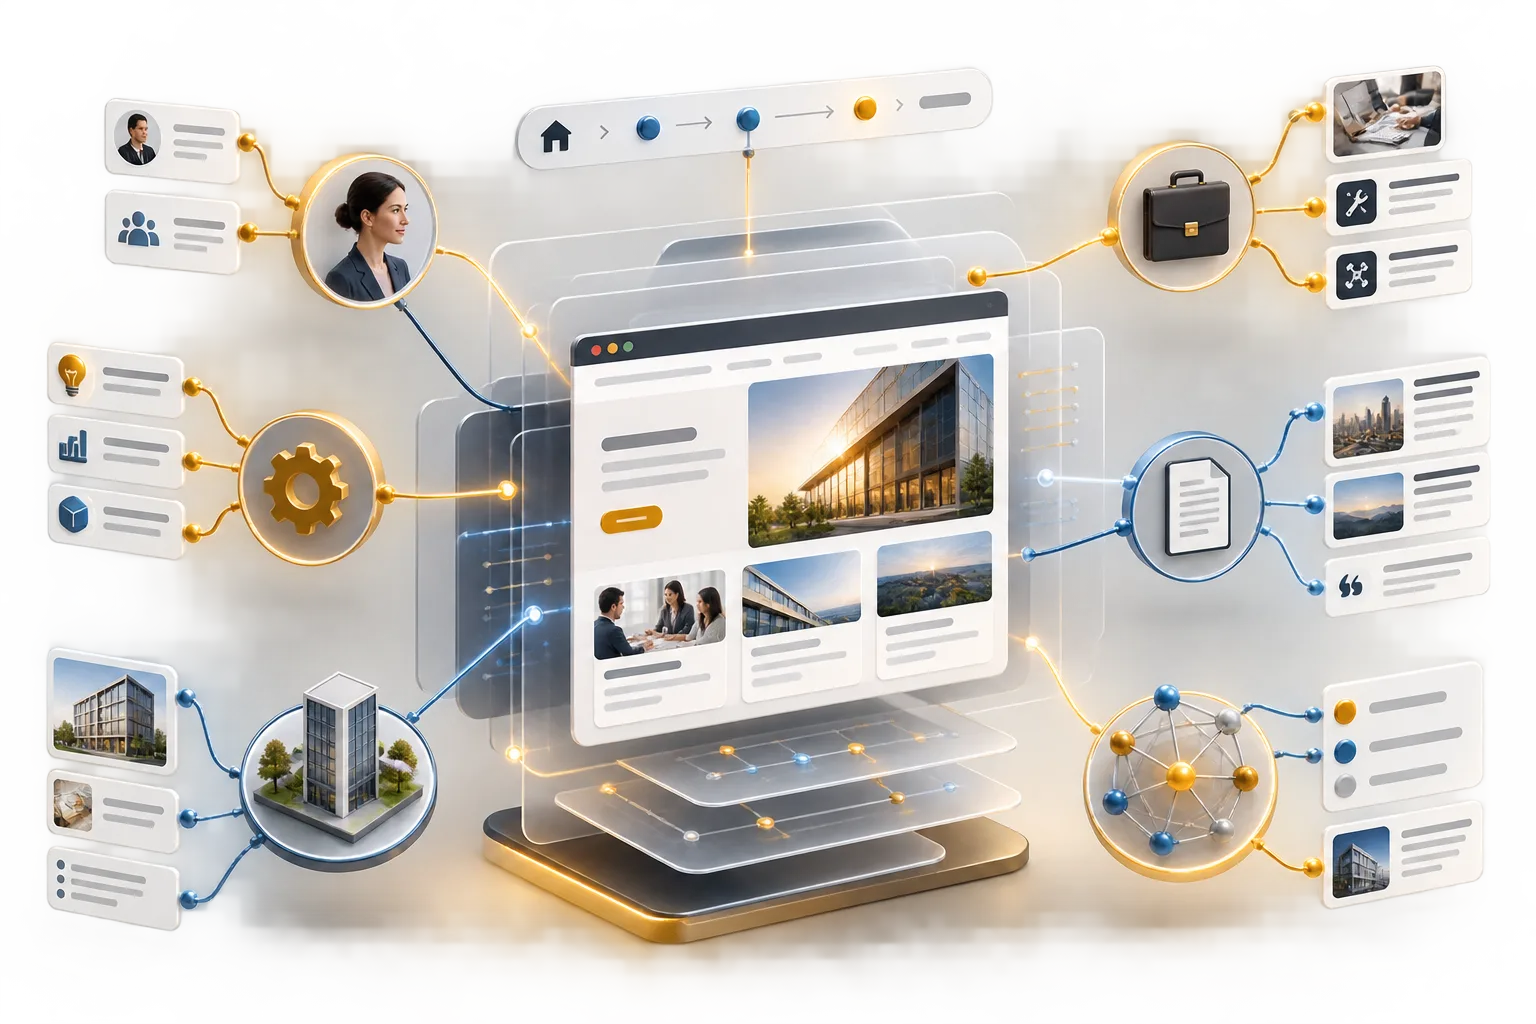
More schema is not automatically better. Marking every section with unrelated types creates noise. Choose the entity that best represents the page, supply accurate required and recommended properties, and validate the output. Structured data can improve eligibility for search features, but it does not guarantee them and does not replace useful content.
Engineer media and metadata together
Images should have descriptive filenames, appropriate dimensions, modern compression, and alternative text that communicates their purpose. Decorative images can use empty alternative text. Avoid stuffing keywords into descriptions. A meaningful editorial image can support understanding, while a large generic image may only delay the content.
Titles and descriptions should be unique, accurate, and written for a searcher evaluating results. A title identifies the page and its distinctive promise. A description summarizes the value and can improve click quality, though search engines may rewrite it. Open Graph and social metadata control how links appear when shared. Canonical URLs should be absolute and consistent with server redirects.
Build a sitemap that reflects reality
An XML sitemap should contain canonical, indexable URLs that the site wants discovered. Exclude drafts, redirects, error pages, and administrative routes. Use accurate modification dates based on meaningful content changes rather than regenerating today’s date for every URL. Split large sitemaps by content type when doing so improves monitoring.
Submission to search tools does not force indexing. It provides discovery and diagnostic information. Compare submitted and indexed counts, inspect representative exclusions, and look for patterns by template. A few intentionally excluded URLs are normal; thousands of unexpected variants suggest an architectural source.
Audit by evidence and impact
A useful technical SEO audit combines several views: a crawl shows reachable structure, server logs show what bots actually request, analytics show human use, search-console data shows impressions and indexing feedback, and source inspection reveals template behavior. No single tool provides the complete truth.
Prioritize findings by expected impact, confidence, effort, and dependency. A sitewide canonical error affecting every project page usually deserves attention before minor metadata preferences on one article. Separate confirmed defects from hypotheses. Provide examples, affected scope, desired behavior, implementation owner, and a verification method. An audit should become an executable roadmap rather than a long inventory of warnings.
After implementation, recrawl the affected templates, inspect responses directly, validate markup, and monitor search data over an appropriate period. Some changes are visible immediately at the server level while search systems require time to revisit and reassess pages. Verification should distinguish deployment success from eventual search outcome.
The foundation for compounding visibility
Technical SEO has its greatest value when it becomes part of development rather than periodic repair. Route design, templates, content models, performance budgets, redirect rules, localization, and publishing workflows all create search signals. Designing those systems intentionally prevents entire classes of defects.
The objective is not to make a site attractive to a crawler at the expense of people. It is to deliver valuable information through an architecture that both can understand. Truthful responses, clear relationships, stable URLs, fast pages, accessible HTML, accurate metadata, and evidence-based monitoring create that shared foundation. Once it exists, every genuinely useful page has a better chance to be discovered, interpreted, and trusted.